

Overfit
Run mixture-of-experts models larger than your device's memory.
Overfit is Noema's paged mixture-of-experts inference. It keeps the parts of a compatible model that every token needs in memory and reads the rest from local storage as each response needs them. This adds capacity, not a guarantee of speed.
Field test
Gemma 4 26B on an iPhone.
A 26B-parameter mixture-of-experts model whose full weights do not fit in an iPhone's memory, answering a multi-step physics problem on the phone itself. Overfit kept the shared layers resident and paged experts from storage as the router asked for them.
The prompt
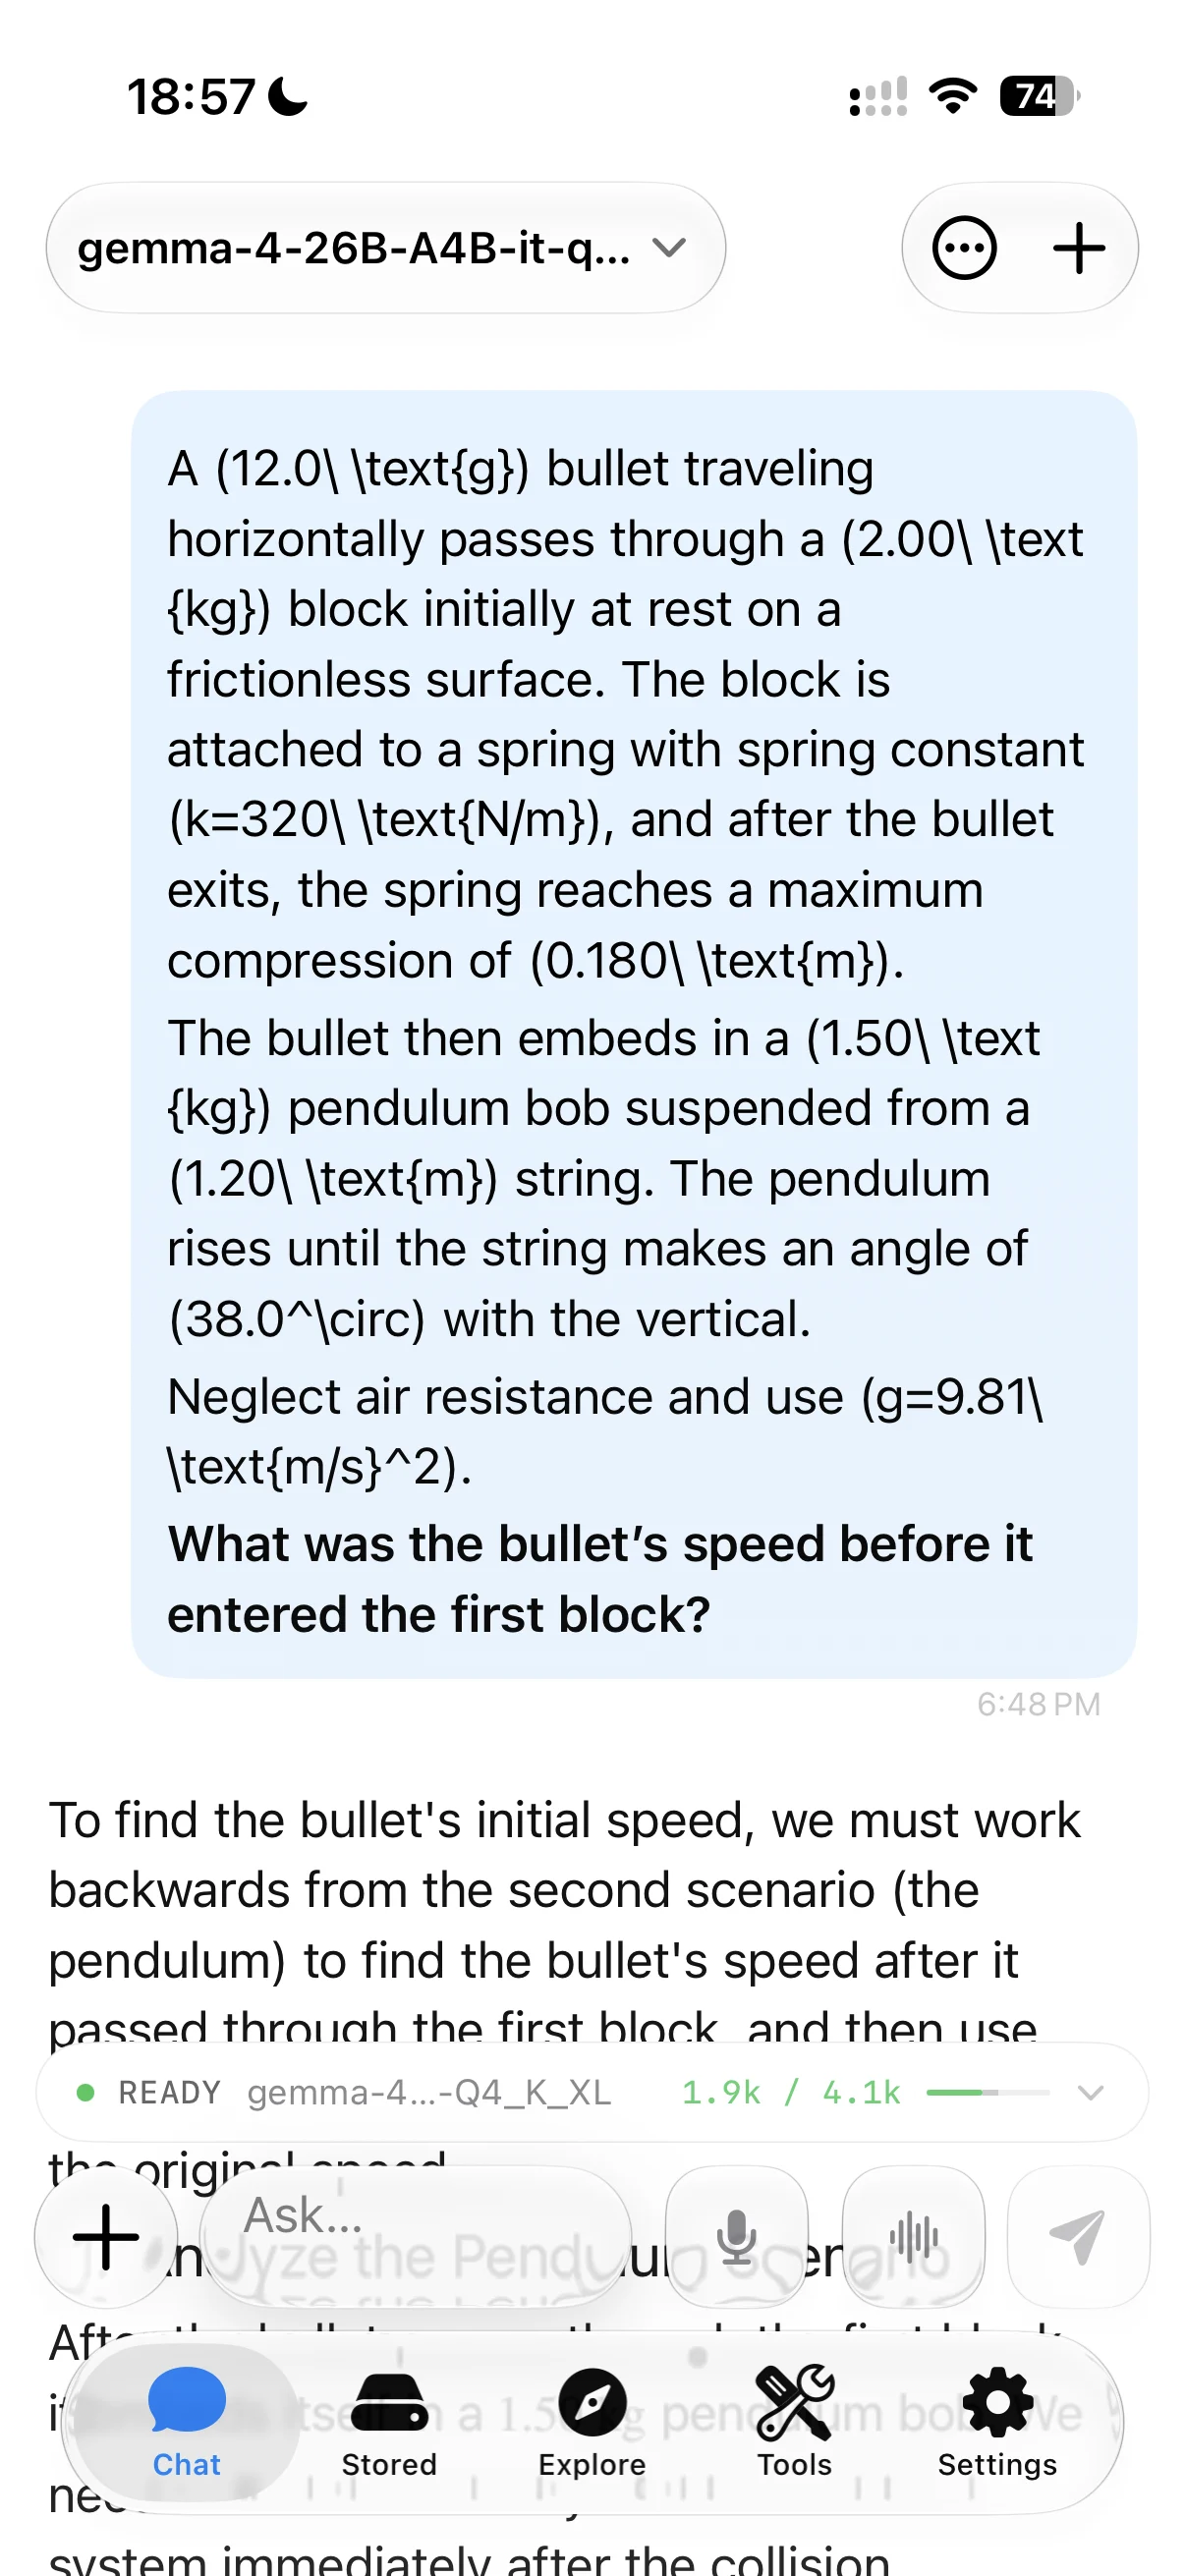
A ballistic-pendulum problem chained across a spring compression and a pendulum swing, sent to Gemma 4 26B-A4B with the model loaded and resident.
The working
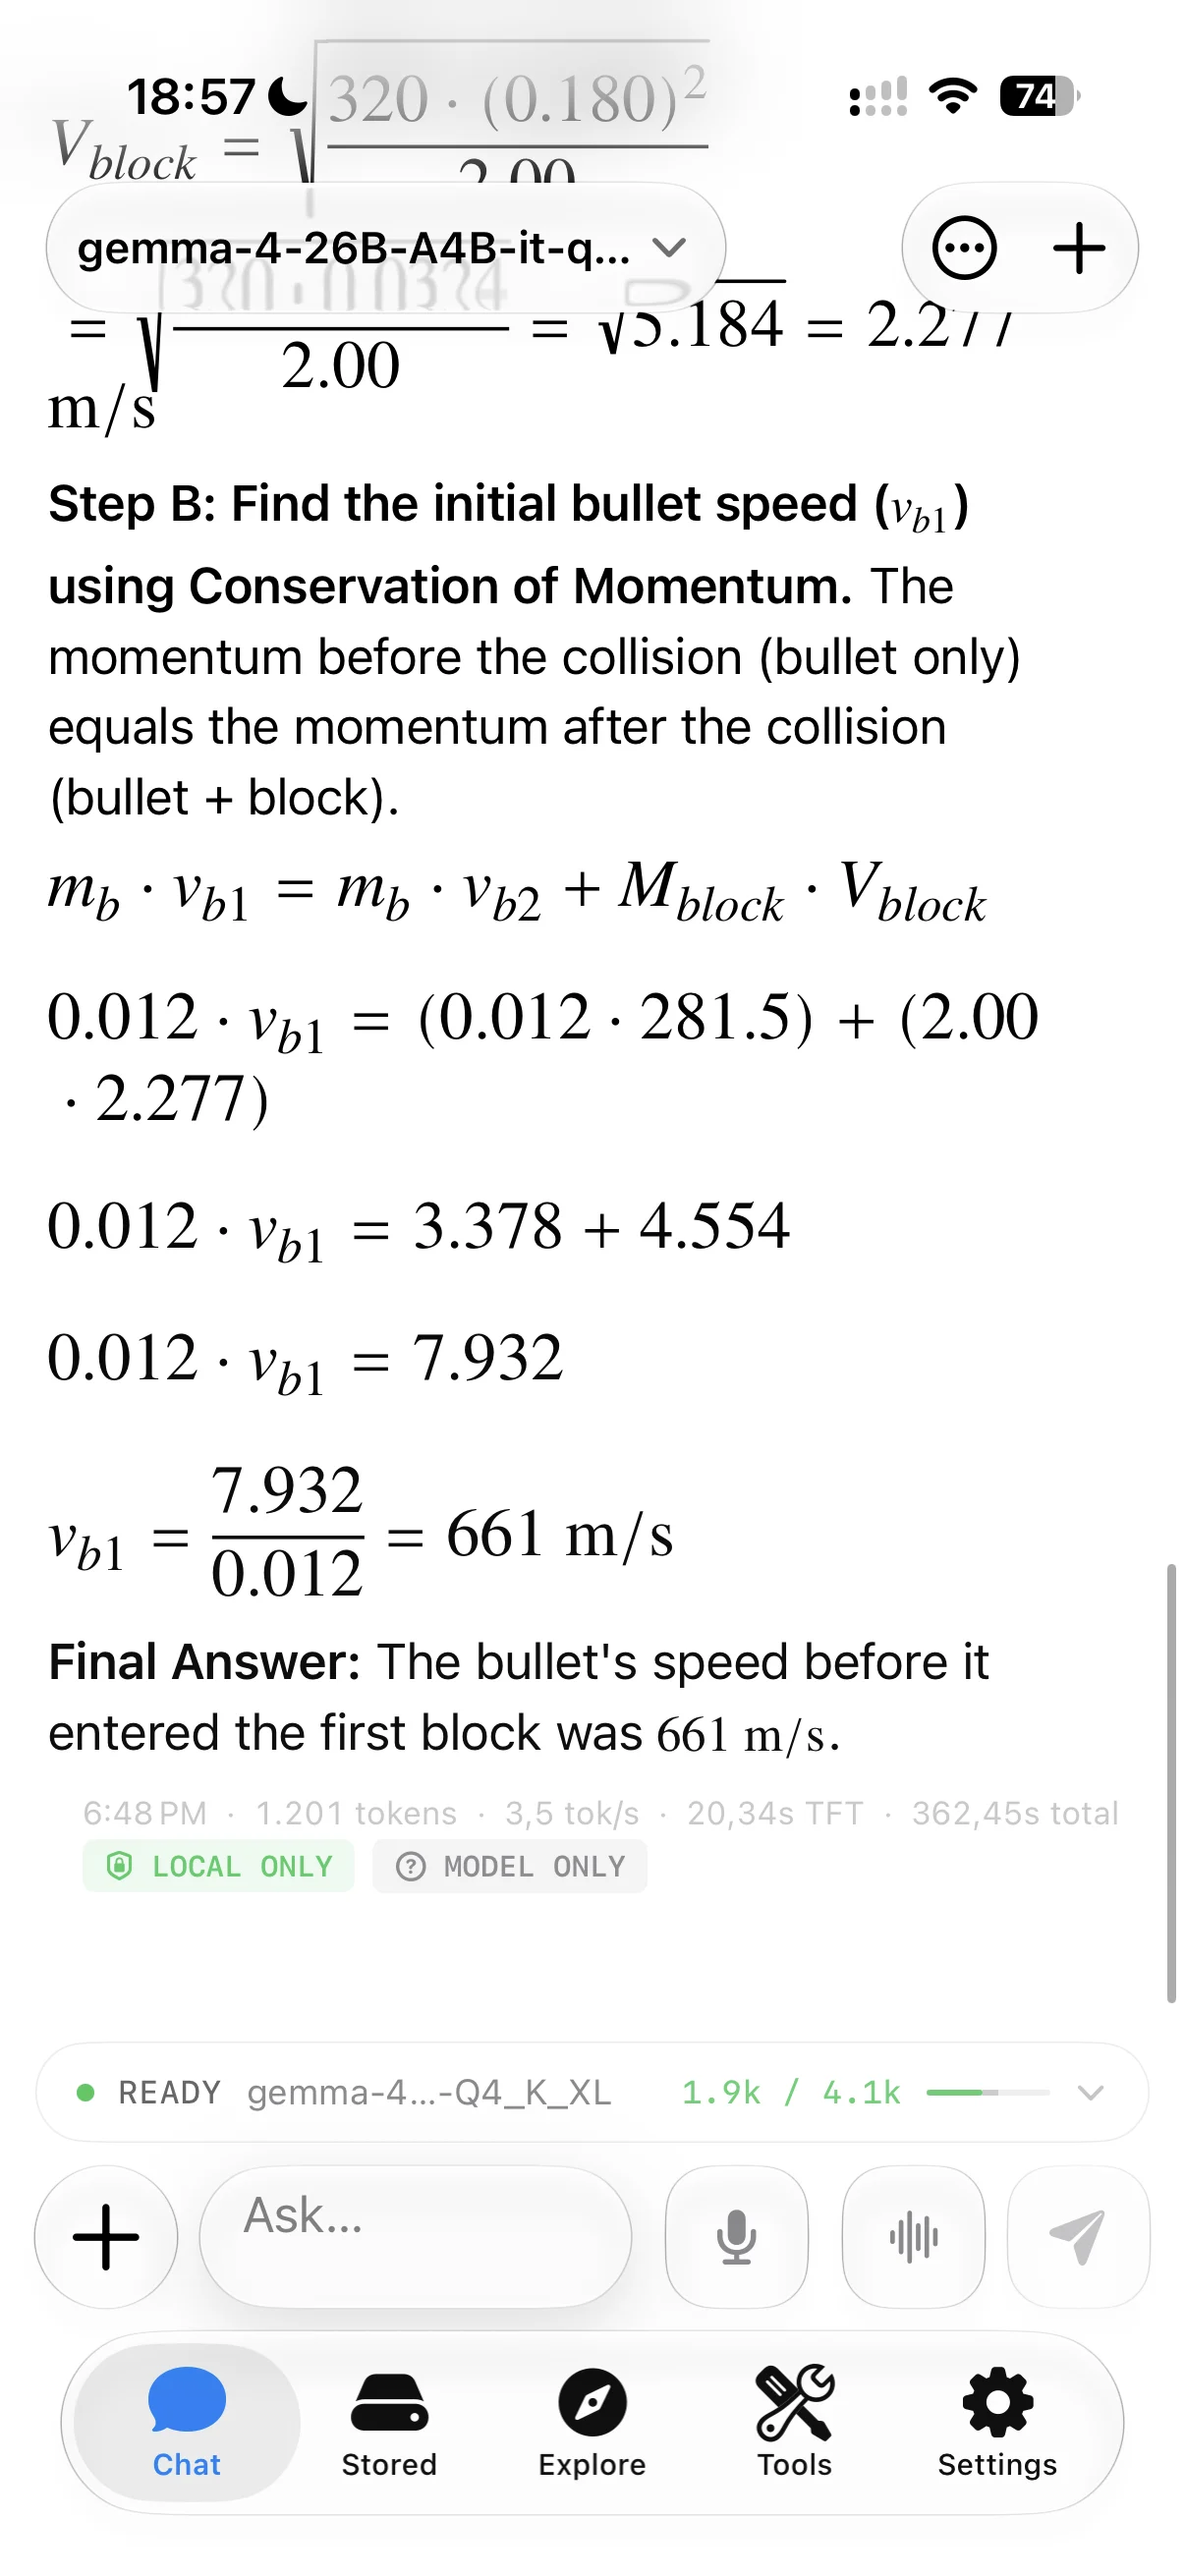
1,201 tokens of momentum-conservation working, generated on the iPhone with experts read from local storage.
The answer
A final answer of 661 m/s. The run footer reports the on-device timings, and the badges confirm the run stayed local.
- Prefill speed
- 34.4 tokens/s
- Time to first token
- 20.34 s
- Generation speed
- 3.5 tokens/s
- Total time
- 362.45 s
- Model
- gemma-4-26B-A4B-it, Q4_K_XL
- Parameters
- 26B total, about 4B active per token
- Device
- iPhone, on device, with no Mac, relay or cloud
- Execution
- Overfit, experts paged from local storage
- Context
- 1.9k of 4.1k tokens used
- Output
- 1,201 tokens
One capture on one device, not a benchmark. Prefill and generation speed depend on storage throughput, available memory, quantization, prompt length, expert reuse and thermal state. A smaller model that fits entirely in memory will still start and generate faster.
How it works
A larger model, loaded in parts.
A mixture-of-experts model is built from many specialist parts, but each token uses only a few of them. Loading every part into memory is often unnecessary.
Get a paged package
Download a complete
.noema-pagedpackage from Explore → GGUF → Noema Overfit, or create one on a Mac from a compatible mixture-of-experts GGUF. Conversion changes how the files are stored and loaded; it does not retrain, prune or replace the model.Reserve memory for this device
At launch, Noema sizes the expert bank for the current device and memory state. More memory means fewer reads from storage. Models that fit normally use the standard loading path.
Read only the active experts
When a token selects an expert that is not in memory, Noema reads it from local storage, verifies it and loads it into the bank. Frequently used experts stay available without memory growing without limit.
Generate on the device
Noema runs the model with its native Apple-silicon runtime. Long prompts are processed in bounded groups, and generation reuses experts already in the bank.
Where it runs
Run packages on every device. Create them on a Mac.
| Task | Supported on |
|---|---|
| Download and run a paged package | iPhone, iPad, Mac and Apple Vision Pro |
| Create a package from a compatible GGUF | Mac only |
| Context for a paged launch | Up to 8,192 tokens on Mac; up to 4,096 tokens on iPhone, iPad and Vision Pro |
Before you rely on it
Test the actual device.
The Canary Test runs the exact package on the device in your hand. Its result belongs to that package, device, storage volume and app build, and can change when any of them does.
What it measures
- Validates a sample of the package
- Measures cached and uncached storage reads
- Runs a fixed 64-token completion
- Records time to first token and generation speed
- Measures latency percentiles and long stalls
- Records expert-bank hit rate, misses per token, peak memory and thermal state
Possible results
- Paged — interactive
- Paged — slow
- Too slow on this device
- Use Constellation
- Not supported for this model
The test is recommended, not mandatory.
Compatible models
Compatibility is limited.
The runtime supports selected Qwen 3, Qwen 3.5, Qwen 3.6, Gemma 4, Poolside Laguna and DeepSeek V4 Flash architectures. It is not a general mechanism for dense models or arbitrary GGUF files.
| Package | Download | Resident core | Expert files |
|---|---|---|---|
| DeepSeek V4 Flash 0731, UD-IQ4_NL | 136.66 GB | 7.81 GB | 128.85 GB |
| Gemma 4 26B-A4B QAT, UD-Q4_K_XL | 14.36 GB | 1.40 GB | 12.96 GB |
| Qwen 3.6 35B-A3B, UD-Q4_K_M | 22.15 GB | 2.57 GB | 19.57 GB |
| Qwen 3.5 122B-A10B, Q4_K_M | 74.27 GB | 4.00 GB | 70.26 GB |
Pre-built packages in the NoemaAI-labs/Noema-Overfit repository as of August 24, 2026. Poolside's Laguna S 2.1 and Laguna XS 2.1 GGUFs can be converted into packages on a Mac.
Privacy and safety
The model and the conversation stay on your device.
What stays local
- Model files remain in local storage, and expert files are excluded from device backups.
- Prompts and responses remain on the device.
- No cloud inference service is required.
Invalid or incomplete files are rejected
Noema checks package structure, sizes and checksums before use, and the native runtime validates the package again at launch. Under memory pressure it can reduce prefetching or stop generation before an unsafe memory condition.
What to expect
More capacity, with tradeoffs.
A model that fits completely in memory will usually start faster, generate faster and use less energy. Overfit is useful when access to a larger model matters more than the lowest latency.
- Storage throughput
- Available memory
- Model architecture
- Thermal state
Documentation
Read the guides.
Noema Overfit
Run compatible Qwen, Gemma, Laguna, and DeepSeek mixture-of-experts models using a resident core and locally paged expert weights, then measure whether the model is practical on your device.
Read the guideRunning models locally
How GGUF, MLX, ExecuTorch, Core ML, and Apple Foundation Models differ, including the Noema 1.5 4B recommendations in 4.2.
Read the guideModel settings
A practical guide to presets, context, sampling, helper models, and format-dependent controls.
Read the guide
Run compatible models locally.
Overfit is part of the Noema app. Browse the pre-built packages on Hugging Face, then run the Canary Test on your device.